Incident & Problem Management
As of 2026-10-06
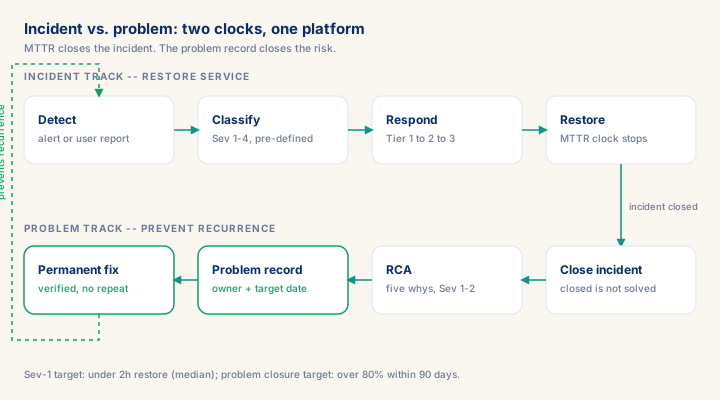
An analytics platform outage is not the moment to investigate root cause — it is the moment to restore service by the fastest safe path, using ITIL's core distinction between incident management (restore service, MTTR-driven) and problem management (permanent fix, prevents recurrence). This module defines a four-tier severity model for Datasphere/SAC/BW incidents, a layered on-call design (Tier 1 first responder through Tier 3 SAP support), the runbook content every platform team must maintain (named runbooks for data-flow failures, HANA OOM, SAC load failures, BW/4HANA process-chain failures), the five-whys RCA method applied to a real incident chain, and the MTTR/problem-closure/repeat-incident metrics that separate mature operations from firefighting. The learner leaves with a severity matrix, an on-call design, and a problem-record governance template.
What you will learn
- Work through a realistic scenario: A European retail group running Datasphere, SAC.
- Recognize and avoid the anti-pattern: Restarting HANA Cloud as the first response to an OOM.
- Apply the module's core decision: Where to draw the Sev-1 line — choose Reserve Sev-1 for total unavailability or a single-point failure hitting all users.
- Track mastery with the KPI: Severity-1 MTTR (median) (target: Under 2 hours; red flag: Median improves while P90 MTTR for the same tier worsens -- the incident mix is being gamed, not the response).
Incident & Problem Management for SAP Analytics Platforms
The distinction between restoring service and preventing recurrence is the core principle of ITIL incident and problem management — and it is frequently collapsed in analytics platform operations, with costly results. An analytics platform outage at 07:30 on a Monday morning, when CFO reporting dashboards are black, is not the moment to investigate root causes. It is the moment to restore service by the fastest safe path. The investigation comes later, in a structured problem record, and produces a permanent fix that prevents the incident class from recurring.
Prerequisites
- Intermediate hands-on experience on SAP analytics projects
- Review core concepts first: C038, C041, C040
Outcomes
- Work through a realistic scenario: A European retail group running Datasphere, SAC.
- Recognize and avoid the anti-pattern: Restarting HANA Cloud as the first response to an OOM.
- Apply the module's core decision: Where to draw the Sev-1 line — choose Reserve Sev-1 for total unavailability or a single-point failure hitting all users.
- Track mastery with the KPI: Severity-1 MTTR (median) (target: Under 2 hours; red flag: Median improves while P90 MTTR for the same tier worsens -- the incident mix is being gamed, not the response).
Full module available to members. The full module adds: the decision framework · the end-to-end scenario walkthrough · the KPI scorecard · the anti-patterns · the code blocks · the knowledge check · the diagrams.